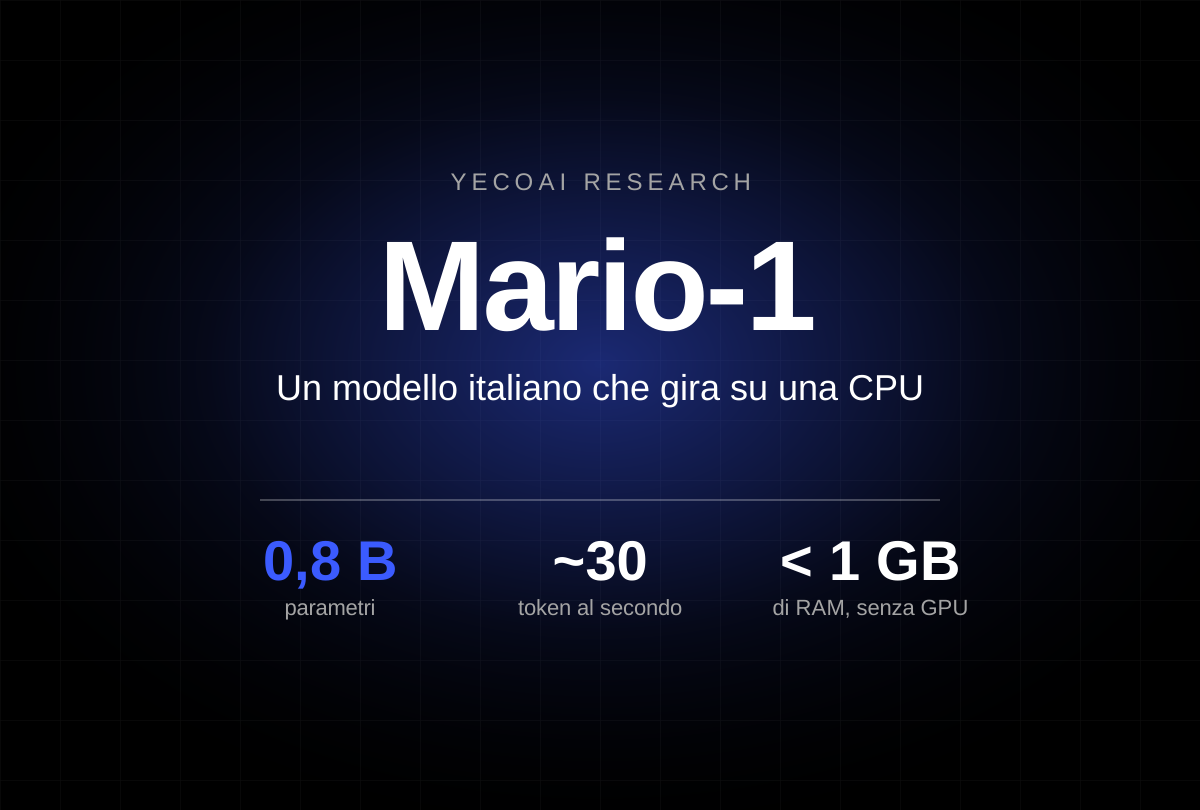
Mario-1: an Italian language model that runs on a CPU
A 0.8-billion-parameter language model built for Italian. It runs on a CPU without a GPU, recognises trick questions, admits what it does not know and does reliable arithmetic.
Research

A small layer that spots when an AI agent gets stuck in a loop and stops it, in about 12 milliseconds.
Anti-Loop Layer is an open-source (Apache 2.0) deterministic monitoring layer for autonomous LLM agents, published as the yecoai-cognitive-layer package. It watches the agent's trajectory from outside the model, no prompts, no fine-tuning, no access to weights, and intervenes when the Thought → Action → Observation loop degenerates into the stochastic failure modes that burn tokens, latency, and user trust: thank-you loops, semantic collapse, and oscillating retries. Typical overhead is ~12ms per cycle with a peak footprint of ~38.85 MB, and the technical whitepaper reports F1 up to 0.90 / 0.71 / 0.63 across detection regimes.
An autonomous agent is a loop: the model thinks, takes an action, observes the result, and repeats until a goal is met. Each element is probabilistic, so the loop as a whole is a stochastic process, and stochastic processes drift. The documented failure modes form a spectrum:
The cost is not only compute. A looping agent holds resources, delays the user, and, in tool-holding agents like our support automation, repeats real actions against real systems. Detecting degeneration early is a safety requirement, not an optimization.
Anti-Loop Layer's core design decision is externality: the monitor sits outside the model's context window and outside its probability distribution. It observes the trajectory, the sequence of states the agent passes through, and applies deterministic signal extraction: textual similarity between consecutive outputs, action repetition rates, and semantic-stability measures across a sliding window. Because the signals are deterministic, behavior is reproducible and auditable: the same trajectory always yields the same verdict, a property stochastic judges (asking another LLM "is this looped?") cannot guarantee.
The layer is passive by default and interventional by policy. In monitor mode it annotates the trajectory with live health metrics. In intervention mode it can halt the loop, force a re-planning step, or escalate to a human, configured per deployment. The intervention contract is explicit: the layer never edits the agent's outputs, only stops or reroutes them.
The whitepaper evaluates detection across regimes that mirror the failure spectrum. Reported results:
Overhead was measured in production-like agent runtimes: ~12ms per monitoring cycle typical, ~38.85 MB peak memory, small enough to run attached to every agent session, not sampled. For DeskNexo, whose verifier pipeline already doubles inference cost by design, a 12ms exogenous monitor was the cheapest safety investment in the stack.
The package installs from PyPI (pip install yecoai-cognitive-layer) and integrates as an exogenous monitor around any agent loop: wrap the Thought → Action → Observation cycle, and the layer emits events (warning, halted, escalated) through a callback interface. Configuration is a policy object: similarity thresholds, window sizes, intervention actions, and escalation targets. The reference implementation, the whitepaper, and the evaluation harness are published for both research and production use under Apache 2.0.
Planned work targets the semantic regime: embedding-based stability signals as a configurable alternative to textual similarity, per-domain threshold auto-tuning from trajectory history, and an anomaly-export format so the layer's telemetry feeds standard observability stacks. The package is versioned independently of YecoAI's products; community issues and PRs are welcome under the Apache 2.0 license.
Agents fail like control systems, not like chats. So we monitor them like control systems: from outside, deterministically, in 12ms.
A 0.8-billion-parameter language model built for Italian. It runs on a CPU without a GPU, recognises trick questions, admits what it does not know and does reliable arithmetic.
Our new model that finds and hides personal data in text. More accurate than the previous version and better than much larger models, especially in Italian. Every release is digitally signed, so you can verify it is genuine.
118.1M-parameter Italian micro-LLM, trained for under €15, ~200 tok/s on CPU. Beats Minerva-350M (3× its size) on BoolQ-IT.